
FamilySearch 探索目錄尋找族譜資源
FamilySearch 目錄。透過 FamilySearch 網站、FamilySearch 圖書館以及選取全球的某個 FamilySearch 中心來找到書籍、紀錄、影像和其他重要資源。

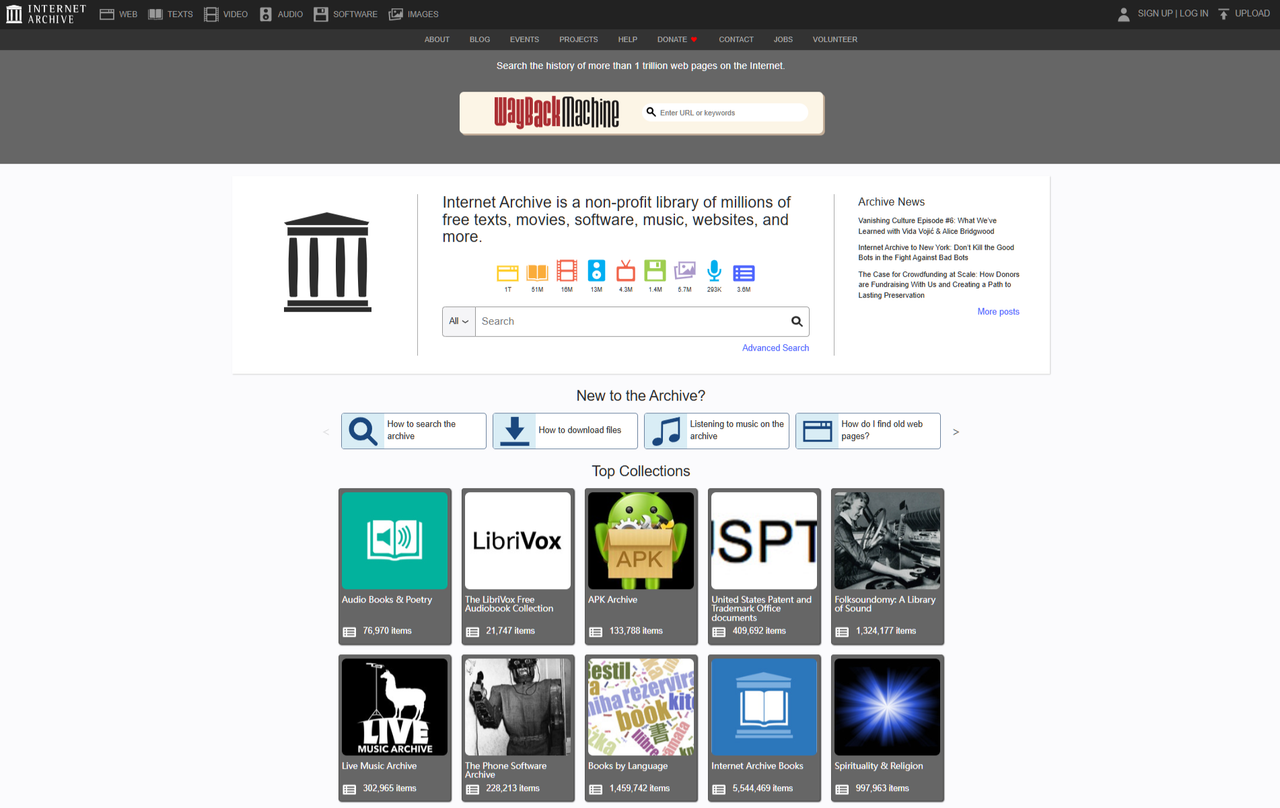
互联网档案馆(英语:Internet Archive)是美国的一个非营利性的、提供互联网多媒体资料档案阅览服务的数字图书馆。互联网档案馆由Alexa创始人布鲁斯特·卡利于1996年创办,总部位于加利福尼亚州旧金山的列治文区,其使命是“普及所有知识”(universal access to all knowledge)。该网站提供的数字资料有如网站、网页、图形材料音乐、视频、音频、软件、动态图像和数百万书籍等的永久性免费储存及获取的副本。
迄至2021年2月,该网站存储了7280 亿个网页、3800万本书和文本、1400 万个录音(包括 240,000 场现场音乐会)、700 万个视频(包括 200 万个电视新闻节目)、400 万张图片、790,000 个软件程序。除此之外,互联网档案馆也是网络开放与自由化的倡议者之一,但其亦遭遇出版商与著作权持有人诉讼,令许多网络的历史纪录被移除。


The Internet Archive, a 501(c)(3) non-profit, is building a digital library of Internet sites and other cultural artifacts in digital form. Like a paper library, we provide free access to researchers, historians, scholars, people with print disabilities, and the general public. Our mission is to provide Universal Access to All Knowledge.
We began in 1996 by archiving the Internet itself, a medium that was just beginning to grow in use. Like newspapers, the content published on the web was ephemeral – but unlike newspapers, no one was saving it. Today we have 30 years of web history accessible through the Wayback Machine and we work with 1,400+ library and other partners through our Archive-It program to identify important web pages.
As our web archive grew, so did our commitment to providing digital versions of other published works. Today our archive contains more than:
Anyone with a free account can upload media to the Internet Archive. We work with thousands of partners globally to save copies of their work into special collections.
Because we are a library, we pay special attention to books. Not everyone has access to a public or academic library with a good collection, so to provide universal access we need to provide digital versions of books. We began a program to digitize books in 2005 and today we scan 3,700 books per day in 22 locations around the world. Books published in or prior to 1930 are available for download, and hundreds of thousands of modern books can be borrowed through our Open Library site. One of the Internet Archive’s missions is to serve people who have difficulty interacting with physical books, so most of our digitized books are available to people with print disabilities (learn about access here).
Like the Internet, television is also an ephemeral medium. We began archiving television programs in late 2000, and our first public TV project was an archive of TV news surrounding the events of September 11, 2001. In 2009 we began to make selected U.S. television news broadcasts searchable by captions in our TV News Archive. This service allows researchers and the public to use television as a citable and sharable reference.
The Internet Archive serves millions of people each day and is one of the top 300 web sites in the world. A single copy of the Internet Archive library collection occupies 200+ Petabytes of server space — and we store at least 2 copies of everything). We are funded through donations, grants, and by providing web archiving and book digitization services for our partners. As with most libraries we value the privacy of our patrons, so we avoid keeping the IP (Internet Protocol) addresses of our readers and offer our site in https (secure) protocol.
This library is a congressionally designated depository for U.S. Government documents. Public access to the government documents collection is guaranteed by public law (Title 44 United States Code).
You can find information about our projects on our blog (including important announcements), contact us, buy swag in our store, and follow us on Twitter and Facebook. Welcome to the library!
Generous funding has come from Foundations including:
The Internet Archive is a member of:


